A green uptime dashboard looks reassuring.
But it can be wrong in the way that matters most.
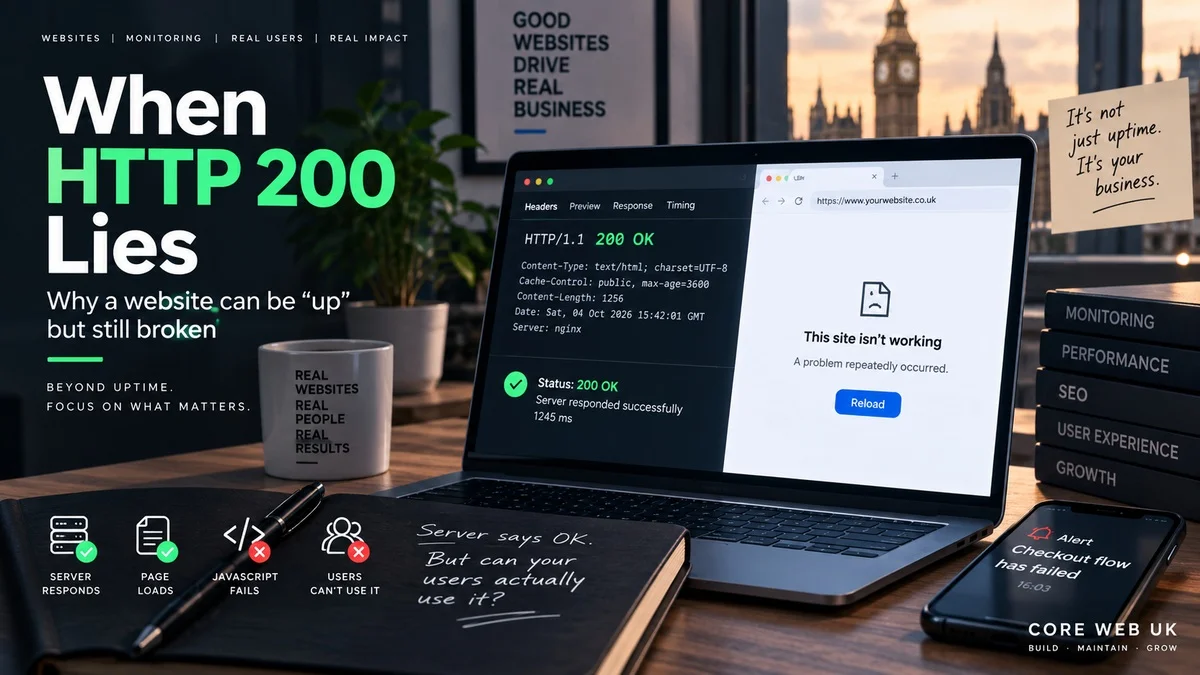
A website can return 200 OK all day and still be broken for the people trying to use it.
The homepage loads. The monitor stays green. The server responds.
Meanwhile, the contact form has stopped sending. Checkout will not complete. A booking widget is blank. A JavaScript error has killed the part of the page that actually matters.
That is the gap this article is about.
“The server responded” and “the website works” are not the same thing.
For me, the useful question is not simply whether a site is online.
It is whether a visitor can still do the thing the site exists for.
What does HTTP 200 actually mean?
200 OK means the request succeeded at the HTTP level.
For a normal GET request, the server returned a representation of the resource that was requested.
That is useful information.
It is just not the whole story.
A 200 response does not tell you whether:
- the right content appeared;
- JavaScript ran properly;
- a form can submit;
- an API returned useful data;
- a customer can pay;
- a user can log in;
- a third-party service is working;
- the page is fast enough to use;
- or the full user journey still works.
The status code is not doing anything wrong.
The problem starts when we read 200 OK as “everything is fine”.
It does not mean that.
A site can be “up” and still be down for the customer
WooCommerce makes this easy to picture.
Imagine a shop after a routine plugin update.
The homepage opens.
Product pages open.
The basket opens.
Your uptime monitor reports 200 OK everywhere.
Then somebody reaches checkout.
The payment fields do not load.
Maybe a JavaScript dependency has failed. Maybe the shipping service is not responding. Maybe a checkout extension has thrown an error after the page was already delivered.
From the server’s point of view, the checkout page worked.
From the customer’s point of view, the shop is closed.
That is a real outage, even if the uptime graph says 100%.
The same thing happens on ordinary business websites.
A local business can have a perfectly healthy homepage while its enquiry form has quietly stopped sending messages.
The owner may not find out until they realise no new leads have arrived for two days.
The website was never technically “offline”.
The part that makes the business money was.
Six failures a basic uptime check can miss
1. The page loads, but the important content is missing
A database call fails.
The theme still loads, so the visitor sees the header, navigation and footer.
The middle of the page is empty.
The server can still return 200.
This can be especially misleading on cached websites, because enough of the page may survive to make everything look normal at first glance.
2. JavaScript breaks after the HTML arrives
Modern websites often send the initial HTML first, then rely on JavaScript for the useful bits.
That might include:
- account dashboards;
- product filters;
- booking tools;
- menus;
- payment fields;
- forms;
- or live data.
A simple uptime check sees a healthy response.
A real visitor sees a broken page.
Modern SPAs can fail after a perfect 200
This becomes even more obvious with modern single-page applications built with React, Vue, Next.js and similar frameworks.
The server or CDN may successfully return the outer HTML shell with a 200 OK response. That shell can be tiny. In some setups, the useful page content is not there yet. The browser still has to download JavaScript, run it and hydrate the page.
If that client-side step crashes, the result can be a completely blank screen even though the network request looked healthy.
A simplified shell might look like this:
<!doctype html>
<html>
  <head>
    <title>Your App</title>
  </head>
  <body>
    <div id="root"></div>
    <script src="/app.js"></script>
  </body>
</html>
The server has done its job. It returned valid HTML and a successful status.
But if app.js fails because of an unhandled runtime exception, a broken deployment, a failed third-party script or an incompatible browser-side dependency, the user may get a white screen with nothing useful on it.
A status checker that only looks for 200 will report success.
A real browser check will show the failure.
That difference matters more as more of the web moves into client-side rendering and hydration.
3. An API returns 200 with bad data
An API can return 200 and still send data that is empty, incomplete or wrong for the application.
The request succeeded.
The result may still be useless.
That is why API checks often need to look at the response body as well as the status code.
Is the expected field there?
Is the value sensible?
Did the API return what the application actually needs?
4. The form is visible, but sending fails
This is one of the quietest failures on a lead-generation website.
The contact page opens.
The form looks fine.
Then the visitor presses Send.
That action triggers another request, and that is where things break.
The cause might be email configuration, an API problem, a plugin conflict, a firewall rule or a broken CRM integration.
If you only monitor the page URL, you will never see it.
5. Checkout breaks at the final step
An online checkout depends on more than one page.
There may be:
- basket logic;
- shipping rates;
- tax rules;
- stock checks;
- payment gateways;
- fraud checks;
- confirmation emails;
- fulfilment systems.
Checking the homepage tells you almost nothing about that chain.
And the closer the failure is to payment, the more expensive the false green signal becomes.
6. The wrong page returns 200
Sometimes the server returns a successful status for the wrong content.
That might be:
- a generic fallback page;
- a maintenance screen;
- a security challenge;
- an empty template;
- or a page saying the requested content does not exist.
The monitor sees 200.
The visitor sees the wrong thing.
This can also affect SEO.
When a lying 200 becomes a soft 404
Google uses the term soft 404 for pages that return a successful response but effectively behave like missing or invalid pages.
A common example is a product or category page where the database query fails quietly. The template still loads, so the server returns 200 OK, but the body says something like “We couldn’t find that product” or contains almost no useful content.
To a basic uptime monitor, the page is healthy.
To a search engine, the page may look empty, broken or equivalent to a genuine 404.
If Google repeatedly sees thin or missing content behind successful status codes, those URLs can be treated as soft 404s rather than valid pages. They may disappear from the index, and crawl time can be wasted on URLs that are not providing useful content.
This is where monitoring and SEO meet.
If Search Console starts reporting unexpected soft 404s, it is worth checking whether templates, database calls, routing or application logic are failing while still returning 200.
A false success can therefore become three problems at once:
- a user-experience problem;
- a monitoring problem;
- an indexing and crawl-efficiency problem.
Content checks are better, but they still have limits
A useful step up from status-only monitoring is a content check.
Instead of asking:
“Did this URL return 200?”
you ask:
“Did it return 200, and is the thing I expect to see actually there?”
For a product page, that might be the product title.
For a login page, it might be the sign-in form.
For a service website, it could be the main enquiry section.
This catches a lot of failures that a simple status check misses.
But it is still not proof that the page works.
A button can say Add to basket and still do nothing.
A login form can appear while authentication is broken.
A checkout page can contain every expected heading while the payment service is unavailable.
Seeing the right words is useful.
Completing the task is better.
A simple content assertion is better than status == 200
Even a basic content check can catch failures that a status-only monitor will miss.
For example, instead of checking only whether the request returned 200, check that the response also contains a piece of content that should always be present.
Here is a simple Node.js example:
const response = await fetch('https://example.com/');
const html = await response.text();

if (response.status !== 200) {
  throw new Error(`Unexpected status: ${response.status}`);
}

if (!html.includes('<title>Your Brand</title>')) {
  throw new Error('Expected page content is missing');
}
The same idea applies in synthetic monitoring tools: test the response code and assert that a unique, stable string is present.
The important word there is stable.
Do not monitor a price, promotional message or date that changes often. Pick something that should reliably exist when the correct page has loaded.
For a rendered JavaScript application, response-body checks may still not be enough. In that case, use a browser-based synthetic test and assert that a real element becomes visible after the page has hydrated.
For example:
await page.goto('https://example.com/');
await page.waitForSelector('[data-test="checkout-button"]', {
  state: 'visible'
});
That moves the test from “Did the server answer?” to “Did the thing the user needs actually appear?”
Monitor the journey, not just the page
This is the part that makes the biggest difference.
Do not only monitor pages.
Monitor the important journey.
For a lead-generation website:
- Open the service page.
- Find the enquiry form.
- Submit a test enquiry.
- Confirm the success message appears.
- Confirm the enquiry arrives where it should.
For an online shop:
- Open a product.
- Add it to the basket.
- Go to checkout.
- Confirm shipping and payment components load.
- Complete a safe test transaction where appropriate.
- Confirm the order reaches the back office.
For a SaaS product:
- Open the login page.
- Sign in with a test account.
- Load the main dashboard.
- Check that expected data appears.
- Perform one safe core action.
These tests take more work than pinging a homepage every minute.
That is fine.
You do not need to run the deepest test against every page.
Run it where failure matters most.
Monitoring should follow the user journey — and, where relevant, the money.
The monitoring stack should match the risk
There is no single check that proves an entire website works.
Good monitoring is layered.
| Check | What it tells you | What it can miss |
|---|---|---|
| HTTP status | The server responded as expected | Wrong or unusable content |
| Content check | Expected text or data appeared | Broken interactions |
| Browser check | The page rendered in a real browser | Multi-step failures |
| Synthetic journey | A critical user task can be completed | Issues affecting only some real users |
| Real-user monitoring | What visitors are actually experiencing | You may learn about the problem after users hit it |
The right mix depends on the site.
A simple brochure site does not need the same monitoring setup as an online shop taking thousands of payments.
WordPress can make a broken site look healthy
Caching adds another layer of confusion.
A WordPress homepage may be cached by the server, a plugin or a CDN.
That cached page can keep loading even when the application behind it has a problem.
So the homepage looks fine.
Then somebody tries to:
- search the site;
- open an uncached page;
- log in;
- submit a form;
- add a product to the basket;
- or start checkout.
That request reaches the live application and fails.
Now you have a strange situation:
- public cached pages look healthy;
- dynamic functions are broken;
- basic monitoring remains green.
For WordPress and WooCommerce, I would always test at least one dynamic path as well as a public cached page.
Which path depends on what the site is there to do.
Health endpoints can give false confidence too
Applications often expose a route such as:
/health
That can be useful.
A monitoring system gets a quick answer about whether the application is alive.
But the health check itself needs to be meaningful.
If it always returns:
{"status":"ok"}
just because the web process is running, it may stay green while the database is unavailable or a critical service is failing.
A useful health endpoint should reflect the dependencies that matter to the application.
At the same time, it should not be so heavy that the health check becomes a problem of its own.
There is a real difference between:
- the process is alive;
- the service is ready;
- the service is actually useful.
Better monitoring should not mean more noise
There is another trap.
The more checks you add, the easier it is to create useless alerts.
If every brief slowdown triggers an emergency message, people stop paying attention.
A one-off failed check during a deployment is not the same as checkout failing for ten minutes across several locations.
Useful alerting usually means:
- retrying before escalating;
- checking from more than one location where it matters;
- separating warnings from critical incidents;
- setting sensible response-time limits;
- confirming when the service recovers;
- and making the alert say what actually failed.
“Website down” is not very helpful.
“Checkout failed on the payment step three times in a row” is.
What I would monitor on a small business website
For a typical small or medium-sized business website, the basics do not need to be complicated.
1. Public availability
Check the homepage and at least one important internal page from outside the hosting environment.
2. Expected content
Make sure a stable piece of important content is present.
Do not use a temporary promotion or a date that changes every week.
3. Response time
A page that takes 20 seconds to load may technically be online.
For the visitor, it might as well not be.
4. SSL and domain health
A healthy application can still disappear because of an expired certificate, DNS mistake or domain issue.
5. The main conversion
If the site exists to generate enquiries, test the enquiry journey.
If it sells, test the purchase journey.
If it provides account access, test login and one important action after login.
6. Important third-party services
Know which outside systems can break the journey.
That may include:
- payment providers;
- booking platforms;
- CRMs;
- authentication services;
- email APIs;
- maps;
- delivery services;
- stock systems.
You do not need a separate monitor for every single dependency.
But your main functional checks should expose the failures that matter.
“Up” needs a proper definition
Before choosing a monitoring tool, ask one simple question:
What does “working” actually mean for this website?
For one business, it means the phone number and opening hours are visible.
For another, it means an enquiry lands in the sales inbox.
For another, it means a customer can pay.
For another, it means a logged-in user can see live account data.
Those are all different definitions of availability.
If the monitor does not know what success looks like, it cannot reliably tell you when success has stopped.
HTTP 200 is not really lying
The title is deliberately provocative.
200 OK is not actually lying.
It is answering a narrow technical question:
Did this HTTP request succeed?
The mistake is turning that into:
Is the whole website working properly?
Those are different questions.
A status code is one signal.
A useful monitoring setup adds enough context to decide whether the service is doing what real users need it to do.
For a modern website, the strongest definition of uptime is not:
“Can I reach it?”
It is:
“Can the user still complete the job they came here to do?”
That is the difference between monitoring a server and monitoring a service.